

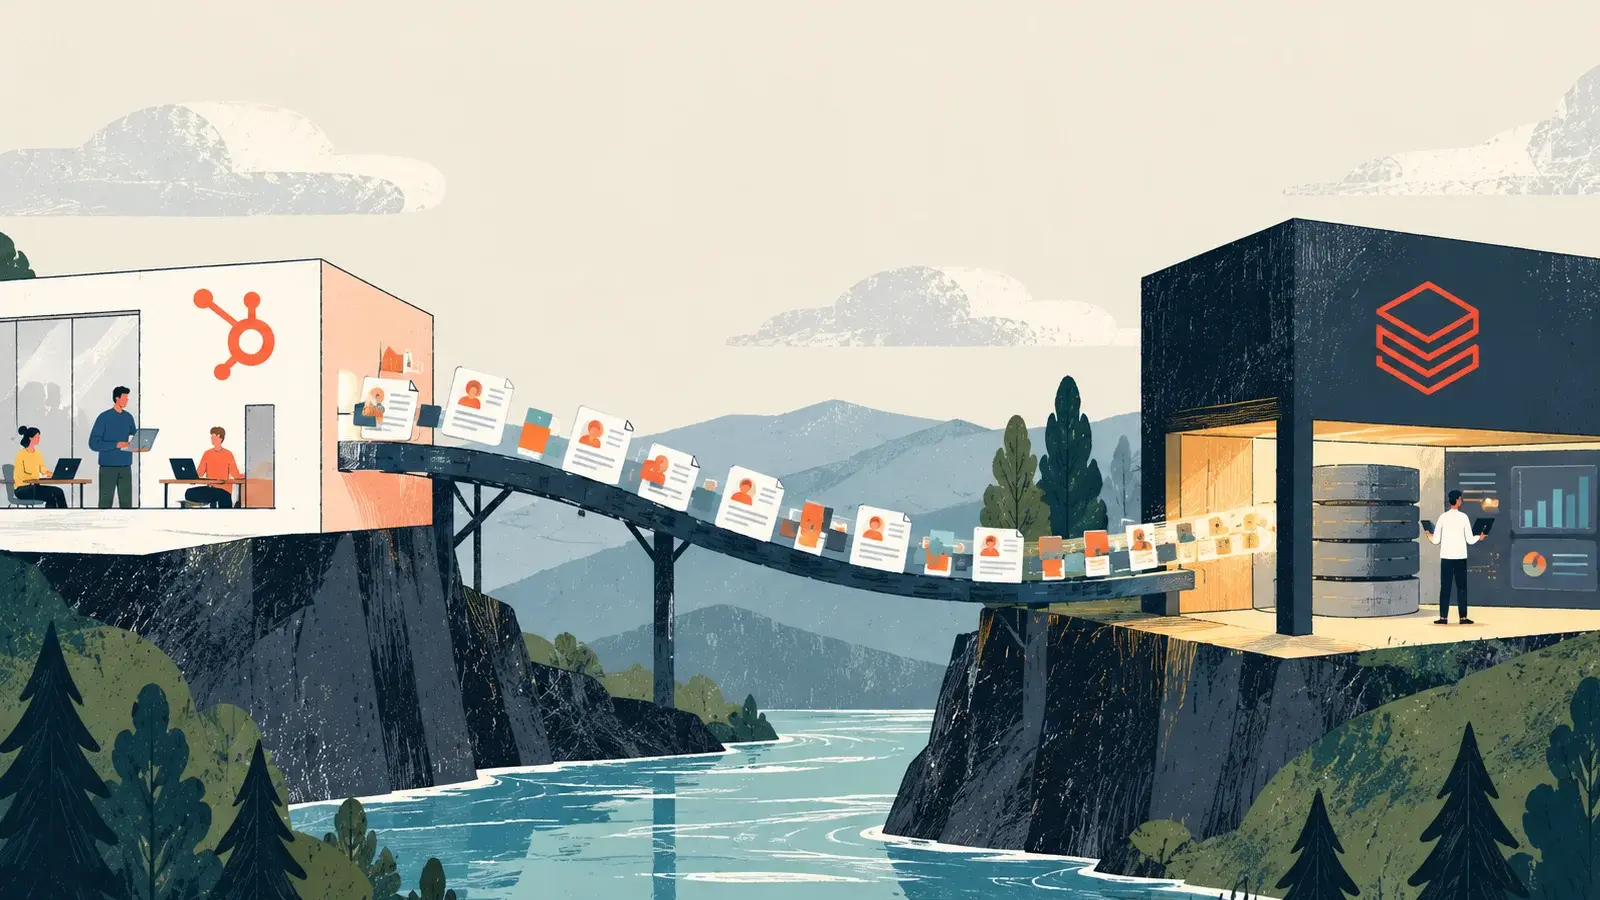
Databricks is a cloud data and analytics platform built around a lakehouse: an architecture that combines the flexible storage of a data lake with the structured reporting capabilities of a data warehouse.
-
It gives teams a place to bring data from different systems together, prepare it for analysis, and use it for reporting and machine learning.
Connecting HubSpot to Databricks lets you analyse CRM data alongside finance, product and operational data.
-
Deals, contacts and campaign activity live in HubSpot, but revenue may sit in the finance system, usage in the product database, and service history somewhere else again.
-
Bringing those sources together helps you answer questions such as which campaigns produced profitable customers, without manually reconciling separate spreadsheet exports.
The connection is only part of the work. HubSpot data is extracted, landed in Databricks in its raw form, transformed into models your analysts can trust, and governed so the right people see the right records.
Why connect HubSpot to Databricks?
HubSpot reporting can only see HubSpot data. Once your CRM data sits in Databricks next to finance, product and operational data, you can answer the questions that cross systems: revenue by original campaign source, customer lifetime value, or churn risk based on how customers actually use your product.
HubSpot's native and custom reports are strong for pipeline, campaign and service reporting inside the CRM. They stop at the edge of the CRM. The consequence is familiar to most data teams: marketing reports on leads, finance reports on revenue, the two never reconcile, and budget decisions get made on whichever report people trust most that week.
Databricks gives those sources one place to meet, with the compute to join, model and analyse them at scale, including long engagement histories that are awkward to report on inside a CRM.
What does Databricks add that a CRM can't do on its own?
Databricks is a lakehouse platform. It stores data in open Delta Lake tables and runs SQL, Python and machine learning on the same data, so your CRM records become one input into a much wider analytical picture.
For CRM data, that brings five practical benefits:
- History over time. Snapshot HubSpot records so you can see how a deal or customer changed over time as well as where it stands today.
- Joined-up analysis. Combine HubSpot with ERP, billing, product and service data in one model.
- Central governance. Unity Catalog manages access control, lineage and auditing across every table in one place.
- AI and machine learning readiness. Build propensity models, forecasting and scoring on governed, joined-up data.
- Cloud choice. Databricks runs on AWS, Microsoft Azure and Google Cloud, which helps you align with existing cloud, security and data residency requirements.
"Connecting HubSpot to Databricks takes more than copying records. You need to preserve the relationships between contacts, companies and deals, handle merged or deleted records, and monitor changes to HubSpot properties. Otherwise, a pipeline can run successfully while the reports it feeds become incomplete or misleading."

If you're still weighing up platforms, our data lakes and architecture page covers when a lakehouse is the right call: data lakes and architecture.
How does HubSpot data get into Databricks?
There are four main routes:
- Databricks' managed HubSpot connector in Lakeflow Connect
- A managed ELT (extract, load, transform) tool such as Fivetran or Airbyte
- HubSpot's data share to Snowflake read into Databricks
- A custom pipeline built on HubSpot's APIs.
The right route depends on which objects you need, how fresh the data must be, and how much control you need over processing.
1. Databricks' managed HubSpot connector
Lakeflow Connect includes a managed HubSpot connector that ingests data straight into the lakehouse and retries automatically when HubSpot rate limits are hit.
-
Check its scope against your needs first. At the time of writing, Databricks documents ingestion from HubSpot Marketing Hub, with CRM object ingestion in beta behind a workspace preview.
-
The connector lands raw data without transformation, some tables can't update incrementally because of how the HubSpot API works, and a column added after the pipeline starts isn't backfilled automatically.
2. A managed ELT tool
Fivetran, Airbyte and similar tools have mature HubSpot connectors and suit teams where HubSpot is one of many sources feeding the lakehouse. They're quick to stand up, and pricing typically scales with data volume, so model the cost against your record counts before committing.
3. HubSpot's data share via Snowflake
On HubSpot's enterprise data tier, HubSpot can share CRM data directly to Snowflake, and Databricks can then read it through a Snowflake connection. This suits businesses already running both platforms. For everyone else, it adds a second platform to license and govern.
4. A custom pipeline on HubSpot's APIs
A custom pipeline extracts data through HubSpot's CRM APIs and uses webhooks to catch changes as they happen. It takes more setup up front, and in return gives you full control over custom objects, associations, deduplication, error handling and sync timing.
What's involved in building the integration?
A HubSpot to Databricks integration is built in four stages: define the questions the data must answer, choose the ingestion route and sync frequency, land the raw data and model it, then govern and monitor it. In our experience, most problems trace back to skipping the first stage, causing extra costs, delays and inefficiencies.
How do you keep CRM data secure in Databricks?
Treat HubSpot data as personal information from the moment it leaves the CRM. Authenticate with the narrowest scopes the pipeline needs, govern access centrally in Unity Catalog, mask or restrict personal fields, and host the lakehouse in a cloud region that meets your privacy obligations.
In practice, that means using a HubSpot app with only the read scopes each object requires, and granting access in Unity Catalog at the catalog, schema and table level. Column masks and row filters keep fields such as email addresses and phone numbers visible only to the people who need them, while lineage and audit logs show who accessed what. For Australian businesses, choose your cloud region with the Privacy Act 1988 and the Australian Privacy Principles in mind, and document where CRM data is stored and processed.
Does this approach only apply to HubSpot?
The same architecture applies to Salesforce, Microsoft Dynamics 365 and most other CRMs. What changes is the connector and the shape of the data model. Lakeflow Connect also has a managed Salesforce connector, Salesforce offers zero copy data sharing with Databricks, and Dynamics 365 data can be exported from Dataverse into cloud storage that Databricks reads. The questions in the four stages above stay the same whichever CRM you run.
How does EIO approach HubSpot and Databricks integration?
We start with the reporting and decisions the business needs, then design the architecture before choosing any tool. That's how we've approached integration work since 2009, and it's why we often recommend a simpler route when one will do.
As a Databricks partner and HubSpot Elite Partner, we build on both sides of the connection. For custom pipelines we use a processing engine designed around HubSpot's batch APIs, with failure logging and alerting through Sentry, selective re-syncs when a mapping changes, and the option to host the pipeline in your own cloud environment and hand it over to your team. If you also need modelled data flowing back into HubSpot, our guide to HubSpot and Databricks reverse ETL covers that direction.
Frequently asked questions